
AI in software development: from code that seems to work to a verified result
Back to blogA practical framework for using artificial intelligence in software development without delegating decisions, security or business knowledge.
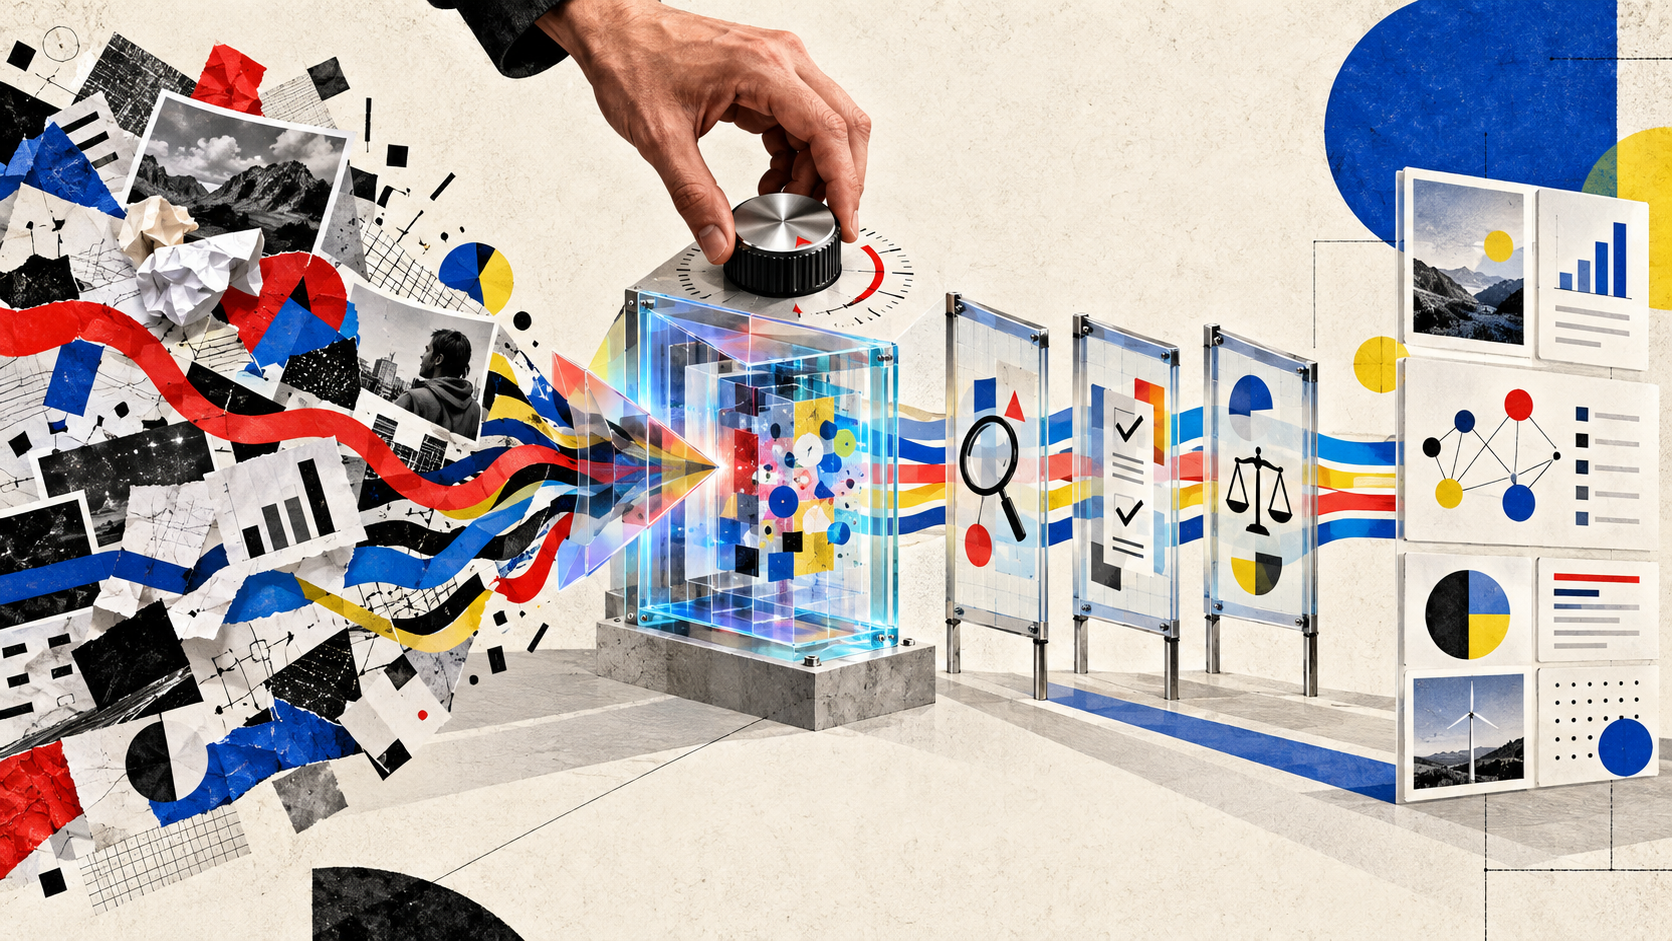
A company needs to export its orders to a spreadsheet. The application already lets users view and filter them by date, status and customer, but the administration team needs to download that same selection to work with it.
We can ask an AI tool to build the export feature. We will probably get code quickly. The question is whether it will export the right orders, respect access permissions and keep working as the volume grows.
This example helps us distinguish where AI is useful from the work we cannot consider finished simply because it has generated a convincing answer.
Before generating anything, find what already exists
The first useful task is to understand how the current query works.
We can use AI to locate the orders screen, follow its request to the server and identify where filters and permissions are applied. It can also help us find other export features in the project and explain which components they use.
That investigation gives us a basis for making decisions. If a query already returns the orders a user is allowed to access, with the appropriate filters applied, we should examine how to reuse it. Creating a separate query for the export can duplicate rules that will then evolve independently.
AI makes exploration easier, but its explanation must be checked against the code. It might find a method with a suitable name and miss the fact that it is no longer used, or mistake a partial permission check for complete access control.
The outcome of this first stage should be a plan we can review: which parts will be reused, which will change and which behaviour must remain intact.
Where it can save work
Once we understand that flow, AI can prepare an initial implementation: add the download operation, build the file using existing utilities and connect the button on the screen.
It can also suggest tests for different filters, identify edge cases and help document decisions.
It adds value here because it is working within clear boundaries. It does not need to invent how the application represents an order, which library it uses to generate files or where access control belongs.
That does not mean its first proposal will be correct. It means we will have something concrete to review, rather than a solution built on assumptions nobody has explained.
A valid file can contain the wrong result
Imagine that AI reuses the request that loads the table. The download works, the file opens and the columns look right.
However, the table displays orders in pages of fifty records. If the export accidentally retains that pagination, it will download only the first fifty orders even when the filter matches two hundred.
It might also interpret the final day of the date range incorrectly. A date converted to midnight could exclude orders received during the rest of that day.
Some errors are even less visible. The button might be hidden from certain users, while the new server operation fails to check their permissions. Hiding an option on the screen does not protect access to the data.
None of these problems will be discovered by checking only that the file downloads.
How to check the result
Before accepting the implementation, we need to define what we expect it to do using known data.
We can prepare a test dataset containing orders with different customers, statuses and dates, including some exactly at the boundaries of the date range. We also need more records than fit on one page and users with different permissions.
With that foundation, the checks have specific expected results:
- The export includes every order that matches the filters, rather than just the visible page.
- Orders outside the date range are excluded, and the boundaries behave according to the agreed rules.
- Each user receives only the data they are allowed to access, even when requesting the download directly from the server.
- Amounts, dates and references retain their intended meaning when the file is opened.
- The existing query and its pagination continue to work after the change.
AI can help write these tests. What we should avoid is letting it derive the expected result exclusively from its own implementation. If it has misunderstood the requirement, it may generate a test that confirms precisely that mistake.
The reference must be the agreed behaviour, rather than the newly generated code.
Review the cost of the solution too
Passing functional tests does not answer every question. An export that works with a hundred orders might consume too much memory with a much larger volume.
We need to check how it retrieves the data, whether it performs unnecessary queries and whether it respects the application's operational limits. Depending on the expected volume, an immediate download may be sufficient, or another mechanism may be needed. There is little point in adding complexity prematurely, but we should not ignore real conditions of use either.
An AI proposal is a contribution to the project and should be reviewed like any other: reuse, clarity, security, dependencies and its impact on what already works.
The value lies in finishing the task properly
In this case, AI can reduce the work involved in exploring the application, prepare repetitive code and broaden the checks we consider. It can be a substantial help.
But the outcome is not “we generated an export feature”. It is that the administration team can download the correct selection, with the right permissions, without losing orders or disrupting existing functionality.
That distinction points to a useful way of incorporating AI into development: use its ability to move work forward while retaining independent criteria for deciding whether the task has been completed properly.
Digital transformation · Educational simulation · Custom development